

Free SPS-C01 braindumps download (SPS-C01 exam dumps Free Updated Jun 16, 2026)
SPS-C01 Dumps for Pass Guaranteed - Pass SPS-C01 Exam 2026
NEW QUESTION # 145
You have a Snowpark Python UDF that performs sentiment analysis on customer reviews. The UDF relies on a pre-trained machine learning model stored as a file in a Snowflake stage. To enhance security, you want to create a secure UDF. Which of the following steps are necessary to achieve this?
- A. Grant READ privilege on the stage containing the model file to the role that owns the secure UDF.
- B. Grant USAGE privilege on the stage containing the model file to the SNOWFLAKE.DATA_GOVERNANCE role.
- C. Ensure the function definition specifies a 'context' parameter to pass security context.
- D. Wrap the UDF creation in a stored procedure with 'EXECUTE AS CALLER to elevate privileges and ensure model access.
- E. When creating the UDF, specify 'secure=True' in the 'CREATE FUNCTION' statement, and explicitly grant USAGE privilege on the stage containing the model file to the role that executes the UDF using 'GRANT USAGE ON STAGE TO ROLE
Answer: A,E
Explanation:
Secure UDFs require explicit grants to access resources. Granting READ privilege on the stage to the UDF owner ensures access during definition. 'secure=True' makes the UDF secure. 'USAGE ON STAGE must be granted to the role executing the UDF to allow it to read from the stage at runtime. 'SNOWFLAKE.DATA GOVERNANCE' role doesn't automatically grant access, and 'EXECUTE AS CALLER is not directly related to granting access to the model file. 'context' is not a standard parameter for UDF definitions and does not manage security context directly.
NEW QUESTION # 146
You are developing a Snowpark application that utilizes a UDF. You need to ensure that the UDF runs with the privileges of the caller (the user executing the query). Which of the following steps are necessary to accomplish this while creating the Snowpark session?
- A. After creating the Snowpark session, execute the SQL command 'ALTER SESSION SET
- B. When creating the Snowpark session, explicitly set the 'privilege' parameter to 'CALLER.
- C. The account administrator needs to explicitly grant the 'CREATE FUNCTION' privilege to the user.
- D. No special steps are required when creating the Snowpark session; the UDF automatically inherits the caller's privileges.
- E. When defining the UDF using Snowpark, ensure the argument is passed in the decorator. Create the Snowpark session as usual.
Answer: E
Explanation:
To ensure a UDF runs with the privileges of the caller, you need to explicitly specify the 'api_caller_identity=sf.Caller.CALLER when defining the UDF using Snowpark. This instructs Snowflake to execute the UDF with the caller's permissions. No special session configurations are needed. Option A is irrelevant for caller's identity. Option B is incorrect as it's not automatic. Option D does not exist. Option E is a valid SQL command but needs to be implemented in Python using 'session.sqr function
NEW QUESTION # 147
You have a Snowpark DataFrame 'df' containing customer data with columns 'customer id', 'name', 'age', and 'city'. You want to filter the DataFrame to include only customers from 'New York' who are older than 30, then extract the 'customer id' and 'name' into a Rows object, and finally print the 'name' of the first row in the Rows object. Which of the following code snippets correctly achieves this using Snowpark Python?
- A.

- B.

- C.

- D.

- E.

Answer: B
Explanation:
The correct answer is C. The code first filters the DataFrame based on the specified conditions. Then, it selects the 'customer_id' and 'name' columns. The 'collect()' method retrieves the data as a list of Rows objects. Finally, correctly accesses the 'name' attribute of the first row in the list. A uses dictionary access which is incorrect for Row objects, B iterates the dataframe and does not get the first row correctly, D accesses the list by index (incorrect approach) and E is only required in scala
NEW QUESTION # 148
A data engineering team is developing a Snowpark stored procedure to perform complex data transformations and load the results into a target table. They want to operationalize this procedure by scheduling it to run daily. Which of the following is the MOST reliable and scalable way to schedule the execution of this Snowpark stored procedure within Snowflake?
- A. Utilize a third-party orchestration tool, such as Airflow, to schedule and monitor the execution of the stored procedure through the Snowflake connector.
- B. Implement a Streamlit application that calls the stored procedure when a button is pressed.
- C. Create a Python script that uses the Snowpark API to connect to Snowflake and execute the stored procedure, then schedule the script using a Linux cron job.
- D. Use Snowflake Tasks to schedule a SQL statement that calls the stored procedure.
- E. Use Snowflake Pipes to ingest data and trigger the stored procedure based on new data arrival.
Answer: D
Explanation:
Snowflake Tasks are the recommended way to schedule stored procedures within Snowflake. They are a native Snowflake feature, providing scalability, reliability, and integration with Snowflake's monitoring and management tools. Airflow is a valid option, but adds external dependencies.
NEW QUESTION # 149
You have a Snowpark DataFrame named with the following schema: 'product_id' (INTEGER), (STRING), 'category' (STRING), 'price' (FLOAT), and 'description' (STRING). You want to perform several data cleaning and transformation steps. Which of the following operations can be efficiently chained together using Snowpark DataFrames to clean null values in 'description', replace special characters in 'product_name' and standardize 'category' values? Select all that apply:
- A. Using the function to remove special characters (e.g., '$', '#, '@') from the 'product_name' column using a regular expression.
- B. Using a UDF (User-Defined Function) written in Python to standardize the 'category' column by converting all values to lowercase and removing leading/trailing spaces.
- C. Manually iterating through each row of the DataFrame and applying Python string manipulation functions to clean the data. (e.g. row['description'] =
- D. Using the method to replace null values in the 'description' column with a default string 'No description available'.
- E. Using the 'coalesce' function to fill null values in 'description' with values from a separate 'backup_description' column (if available).
Answer: A,D,E
Explanation:
Options A, B, and D can be efficiently chained using Snowpark DataFrame operations. Option A Cna.fill()') is a built-in method for handling null values. Option B is a SQL function available in Snowpark for string manipulation. Option D ('coalesce()') effectively fills null values from another column if present. Option C, using a UDF for string standardization, is viable but potentially less efficient than using built-in functions if possible. Option E is extremely inefficient as it forces data transfer to the client and row-by-row processing instead of leveraging Snowflake's parallel processing capabilities. Chaining operations allows Snowpark to optimize the execution plan and potentially perform these transformations in a single pass over the data. UDF execution might introduce overhead.
NEW QUESTION # 150
You have a Python function that calculates a complex statistical measure on a given row of a DataFrame. You want to apply this function to each row of a Snowpark DataFrame in a distributed manner. Which of the following is the MOST efficient way to achieve this?
- A. Use Snowpark's 'sprocs feature to create stored procedure and call the Python function.
- B. Iterate through the rows of the Snowpark DataFrame and call the Python function on each row individually.
- C. Create a Pandas UDF (User-Defined Function) using decorator and apply it to the Snowpark DataFrame.
- D. Use the "map' method on the Snowpark DataFrame's underlying RDD (Resilient Distributed Dataset) and pass the Python function as an argument.
- E. Use the 'apply' method on the Snowpark DataFrame, passing the Python function as an argument.
Answer: C
Explanation:
Pandas UDFs (User-Defined Functions) are designed for efficient row-wise operations on Snowpark DataFrames. The @pandas_udf decorator enables Snowpark to execute the function in a distributed manner across Snowflake's compute resources, maximizing performance for row-by-row calculations. 'apply' method doesn't exist directly on Snowpark DataFrames. Iterating through rows (Option C) is extremely inefficient. Option D involves RDD which is not exposed directly with Snowpark DataFrames. While option E is an alternative it introduces unnecessary overhead.
NEW QUESTION # 151
You have a Snowpark Python stored procedure that performs complex data transformations. This stored procedure needs to read data from a large table ('TRANSACTIONS) and write the transformed data to another table PROCESSED TRANSACTIONS'). You want to optimize the performance of this stored procedure by leveraging Snowpark's features for parallel processing. Which of the following approaches can significantly improve the performance of the stored procedure, assuming sufficient warehouse resources are available?
- A. Use Snowflake's standard SQL queries within the stored procedure to read and transform the data. Write the results to the 'PROCESSED TRANSACTIONS table using 'INSERT statements.
- B. Read the entire 'TRANSACTIONS table into a Pandas DataFrame within the stored procedure and perform the transformations using Pandas functions. Then, write the transformed data back to the table using Snowpark's 'createDataFrame' and 'write' methods.
- C. Use Snowpark's 'sprocs decorator with appropriate 'packages' and leverage the Snowpark DataFrame API with vectorized UDFs to transform the data. Use 'session.write_pandaS to write the Pandas DataFrame to the 'PROCESSED_TRANSACTIONS' table after the transformation.
- D. Load the data from 'TRANSACTIONS' table into a temporary table within the stored procedure, then use standard SQL queries on the temporary table for transformations, finally using snowpark DataFrame API to write it back to the 'PROCESSED_TRANSACTIONS' table.
- E. Use the Snowpark DataFrame API to read the 'TRANSACTIONS' table and apply transformations using vectorized UDFs. Then, use the 'write' method to write the transformed data to the 'PROCESSED TRANSACTIONS' table.
Answer: E
Explanation:
Using Snowpark DataFrame API along with vectorized UDFs leverages Snowflake's distributed processing capabilities for parallel execution, greatly enhancing performance. Reading the entire table into a Pandas DataFrame (Option B) limits parallelism and can lead to memory issues with large datasets. While SQL queries (Option C) work, they don't fully leverage Snowpark's optimized data transfer and processing. Option D refers to 'session.write_pandas' which isn't accurate in the context of writing transformed Snowpark data to Snowflake tables within the stored procedure. Using a temporary table and standard SQL queries, while functional, doesn't harness the full potential of Snowpark's distributed execution engine as effectively as using the DataFrame API directly (Option E).
NEW QUESTION # 152
You are tasked with optimizing a Snowpark application that processes sensor data'. The data includes timestamp, sensor ID, and sensor reading. Your initial implementation uses a regular Python UDF to calculate the moving average for each sensor. However, the processing time is significantly slow due to the large volume of data'. Which of the following strategies would be MOST effective in improving the performance of this calculation using vectorization?
- A. Increase the warehouse size without modifying the UDF code.
- B. Rewrite the calculation logic using Snowpark's built-in aggregation functions instead of a UDF.
- C. Convert the Python UDF to a Java UDF.
- D. Convert the existing Python UDF into a vectorized UDF using the '@vectorized' decorator, ensuring the input and output are Pandas Series.
- E. Replace the Python UDF with a SQL UDF as SQL UDFs are inherently faster.
Answer: D
Explanation:
Converting the Python UDF to a vectorized UDF allows it to process data in batches (as Pandas Series), which significantly reduces the overhead of transferring data between Snowflake and the UDE While increasing warehouse size (C) can provide some performance gain, vectorization (B) directly addresses the inefficiency of processing individual rows. Using built-in aggregation (D) is also a good option if feasible, but if a custom moving average calculation is required, vectorized UDF is the best fit. SQL UDFs aren't always faster and don't inherently vectorize. Java UDFs may provide some improvement but are more complex to implement than vectorized Python UDFs.
NEW QUESTION # 153
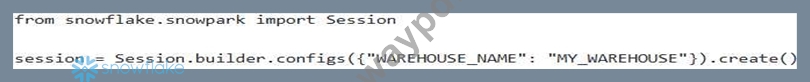
You are tasked with creating a Snowpark session that utilizes a specific Snowflake warehouse for all operations. Which of the following code snippets BEST demonstrates how to correctly specify the 'warehouse' parameter when creating a session using snowpark.Session.builder.configs'?
- A.

- B.
- C.

- D.

- E.

Answer: D
Explanation:
The correct parameter name for specifying the warehouse in the 'configs' dictionary is 'warehouse'. The other options either use incorrect key names (SNOWFLAKE_WAREHOUSE, snowflake.warehouse, WAREHOUSE_NAME) or an incorrect method call (.config instead of .configs). The code snippets provided demonstrate the correct and incorrect methods for specifying the warehouse parameter during Snowpark session creation. Option A correctly utilizes the 'warehouse' parameter within the 'configs' dictionary passed to the Session builder.
NEW QUESTION # 154
You are working with a Snowpark DataFrame containing employee data, including columns 'employee_id', 'first_name', 'last_name', 'salary', and 'department'. You need to perform the following transformations: 1. Concatenate 'first_name' and into a new column called separating them with a space. 2. Increase each employee's salary by a percentage based on their 'department'. Department 'Sales' gets a 10% raise, 'Marketing' gets a 15% raise, and all other departments get a 5% raise. 3. Create a new column reflecting this raise. Which of the following Snowpark code snippets achieves these transformations correctly and efficiently? (Select all that apply)
- A.

- B.

- C.

- D.

- E.

Answer: A,D
Explanation:
Options A and C are correct. Option A uses 'concat for string concatenation and 'when' for conditional salary calculation, which is a standard and efficient approach in Snowpark. Option C uses a Snowflake expression to achieve the same conditional salary calculation, which can be more concise for complex conditions and may leverage Snowflake's optimization. Option B is incorrect, because the '+' string concatenation will not work; string concatenation in Snowpark should happen using the 'concat' function. Option D is less efficient because it uses a Python UDF, which involves serialization/deserialization overhead. Option E will not work because of syntax 'select(' 'Y does not exist, therefore the user will need to specify all the columns. Also, there is a column called ' ' which will break the processing.
NEW QUESTION # 155
You are tasked with optimizing a Snowpark Python application that performs complex data transformations on a large dataset. The application is running slower than expected, and you suspect that data serialization and transfer between the Snowpark client and the Snowflake engine are bottlenecks. Which of the following strategies could you implement to improve performance? (Select all that apply.)
- A. Utilize smaller batch sizes when writing data back to Snowflake to reduce memory pressure on the client.
- B. Convert all dataframes to Pandas dataframes locally and perform data manipulation with Pandas methods to take advantage of local resources.
- C. Create and utilize temporary tables within Snowflake to store intermediate results of complex transformations.
- D. Increase the configuration parameter to maximize parallelism within the Snowpark engine without considering resources or potential bottleneck.
- E. Minimize the amount of data transferred between the client and the engine by pushing down as much computation as possible to Snowflake using Snowpark DataFrame operations.
Answer: A,C,E
Explanation:
Options A, B, and C are correct strategies. Pushing down computation (A) reduces data transfer. Using smaller batch sizes (B) can reduce memory pressure, especially for large datasets. Using temporary tables (C) allows intermediate results to be stored and processed entirely within Snowflake, avoiding unnecessary data transfer. Option D is incorrect because converting to Pandas DataFrames brings the data to the client, negating the benefits of Snowpark's distributed processing. Option E is dangerous since it could cause bottleneck if the resources are not managed correctly.
NEW QUESTION # 156
You are working with Snowpark to create a DataFrame from a Python dictionary where keys represent column names and values are lists representing column data'. However, the dictionary contains lists of varying lengths for different columns. You need to create a DataFrame from the Python dictionary but are unsure how to create it. Which approach should you take and why?
- A. Create a Pandas DataFrame from the dictionary first. Pandas handles lists of unequal lengths by filling the shorter lists with NaN. Then, convert the Pandas
- B. DataFrame to a Snowpark DataFrame using 'session.createDataFrame(pandas_df)'. Snowpark does not support creating DataFrames directly from dictionaries with lists of varying lengths. The code will throw an error. So, manually build the logic of combining the lists.
- C. Attempt to create the DataFrame directly using 'session.createDataFrame(data)'. Snowpark will automatically pad the shorter lists with 'NULL' values to match the length of the longest list.
- D. Transform the dictionary into a list of dictionaries or tuples, padding the short lists with 'None' values. Then, define a schema and use 'session.createDataFrame(data, schema=schema)' to create the DataFrame.
- E. Manually pad all lists in the dictionary with 'None' values until they have the same length. Then, create the DataFrame using 'session.createDataFrame(data)'.
Answer: D,E
Explanation:
Options B and E are the most appropriate solutions. Correctness and Rationale: Option B works. The reason is that padding all the lists to the same length will then allow the function to run correctly Correctness and Rationale: Option E also works. The reason is that the transformation to the dictionary to a list or tuple along with the 'session.createDataFrame(data, schema=schemay is also supported. The data types can be forced too to conform to datamodel. Option A is incorrect because it doesn't state an error. Option C, though technically functional by leveraging Pandas, is less efficient than creating Pandas DataFrame since Pandas creates another layer on top of Snowpark Option D is incorrect because Snowpark does support this scenario provided all lists are of equal length, with padding applied.
NEW QUESTION # 157
A data engineering team is using Snowpark Python to build a data pipeline. They need to create a User-Defined Function (UDF) that transforms a JSON string column representing customer information into a STRUCT type containing flattened fields for 'name', 'age', and 'city'. The UDF should handle null values gracefully and return NULL if the input JSON is invalid or if the 'name' field is missing. Considering performance implications and error handling, which of the following approaches is MOST optimal for defining and registering this UDF?
- A. Using 'snowflake.snowpark.functions.udf with defining the STRUCT schema explicitly, and handling JSON parsing and field extraction using the 'snowflake.snowpark.functions.parse_json' function. Return None for invalid json.
- B. Using 'snowflake.snowpark.functions.sproc' to create a stored procedure that performs the JSON transformation and returns the transformed data.
- C. Using 'snowflake.snowpark.functions.udf with and relying solely on Snowflake's built-in JSON functions within the UDF, even for complex transformations, and handling exceptions with try-except blocks within the UDF to return NULL.
- D. Using 'session.register_function' to register a Python function as a UDF with and manually constructing a VARIANT object in Python from the extracted JSON fields.
- E. Using 'snowflake.snowpark.functions.udf with and handling JSON parsing and field extraction using standard Python libraries within the UDF, returning a JSON string representation of the STRUCT.
Answer: A
Explanation:
Option B is the most optimal. Using allows Snowpark to understand the schema of the returned data, enabling efficient type checking and query optimization. 'snowflake.snowpark.functions.parse_json' leverages Snowflake's internal JSON parsing capabilities, leading to better performance. Returning None from UDF handles nulls gracefully. Other options either involve less efficient StringType return types, manual VARIANT object creation which is less type-safe, or suggest stored procedures when a simple UDF is sufficient.
NEW QUESTION # 158
You are working with a data science team that needs to create Snowpark DataFrames from various file types (CSV, JSON, Parquet, and XML) stored in different locations (internal stages, external stages on AWS S3, and Azure Blob Storage). The team wants a unified and reusable function to create DataFrames, abstracting away the specific file format and location details. Which of the following approaches using Snowpark Python API will provide the MOST flexible and maintainable solution?
- A. Implement a single function that uses a series of 'if/elif/else' statements to determine the file type and location, then calls the appropriate 'session.read' method with the corresponding options.
- B. Use the 'session.sqr method with dynamically generated SQL queries that include the file format and location details. Construct the SQL query string based on the input parameters.
- C. Create a class hierarchy with an abstract base class 'DataFrameReader' that defines a 'read_file' method. Implement subclasses for each file format and location, overriding the 'read_file' method with the specific logic for that format and location.
- D. Create a generic function str, file_format: str, options: dicty that uses 'getattr(session.read, file format)' to dynamically call the appropriate 'session.read' method based on the 'file_format' parameter. Pass additional configuration through the 'options' dictionary.
- E. Create separate functions for each file type and location combination (e.g.,
Answer: D
Explanation:
Option C provides the best balance of flexibility, maintainability, and conciseness. Using 'getattr(session.read, file_format)' allows dynamically calling the appropriate 'session.read' method (e.g., 'session.read.csv', 'session.read.json') based on a string parameter. Passing additional configuration through a dictionary allows customizing the read operation without modifying the core function. Options A, B, D, and E are less flexible, more verbose, or less efficient.
NEW QUESTION # 159
You are tasked with developing a data pipeline using Snowpark that involves reading data from multiple CSV files, performing transformations using Pandas DataFrames, and then loading the transformed data into a Snowflake table. You want to optimize the process by leveraging the capabilities of Snowpark and Pandas effectively. Which of the following approaches is the MOST efficient for creating the Snowpark DataFrame from the pandas dataframe? (Select all that apply.)
- A. Read each CSV file into a Pandas DataFrame, perform transformations, and then create a temporary table with the result of 'session.write_pandas' with auto create table=False' .
- B. Read each CSV file into a Pandas DataFrame, perform transformations, and then create a Snowpark DataFrame from each Pandas DataFrame using Union all the Snowpark DataFrames.
- C. Read each CSV file into a Pandas DataFrame, perform transformations, and then create a temporary table with the result of 'session.write_pandas' with auto create table=True' .
- D. Read each CSV file into a Pandas DataFrame, perform transformations, concatenate all Pandas DataFrames into a single Pandas DataFrame, and then create a Snowpark DataFrame using 'session.createDataFrame()'.
- E. Read each CSV file directly into a Snowpark DataFrame using 'session.read.csv()' , perform Snowpark DataFrame transformations, and then write to the Snowflake table. Avoid using Pandas DataFrames altogether.
Answer: C,E
Explanation:
Option C is the most efficient when the transformations can be effectively done using Snowpark itself, bypassing Pandas entirely and leveraging Snowflake's compute power directly. Option D, while using Pandas for transformation, optimizes data transfer using the optimized 'write_pandas' function. Creating Snowpark DataFrames from Pandas DataFrames and then unioning (Option B) can be less performant due to data transfer overhead. Concatenating Pandas DataFrames and then creating a Snowpark DataFrame (Option A) can be memory-intensive. Option E is incorrect, setting will throw an error if table does not exist.
NEW QUESTION # 160
You are working with a Snowpark DataFrame that contains product information including 'product_name' and 'description'. You need to create a new column named 'search_terms' that contains the first three words from the 'description' column, converted to lowercase. If the description has fewer than three words, the 'search_terms' column should contain all the words available. The words should be separated by a space. What is the MOST efficient way to achieve this using Snowpark?
- A.

- B.

- C.

- D.

- E.

Answer: D
Explanation:
Using a UDF (Option C) is a valid approach, but generally less efficient than leveraging built-in functions or existing Snowflake functions, especially for large datasets, because it involves serialization and deserialization between Python and Snowflake. Option A is not dynamic and will error on strings with fewer than three words. Option D will only correctly return the words if there are exactly three, otherwise it won 't match. E will just return the lowercased string and Snowflake UDF defined in SQL. Snowflake UDFs overhead, and are preferable for performance It is also less efficient than a UDF/Stored proc as it involves calling the Regex. Option is incorrect. Option B (UDF) is the most efficient, assuming GET FIRST THREE_WORDS is a are optimized for execution within the Snowflake environment, minimizing data transfer compared to Python UDFs in Snowpark.
NEW QUESTION # 161
You have a Snowpark DataFrame 'product_df and you want to create a view named 'active_products' that only includes products with a 'status' column value equal to 'ACTIVE'. This view should be accessible to all users in the 'PUBLIC' role. Which of the following code snippets correctly creates the view and grants the necessary privileges?
- A.

- B.

- C.

- D.

- E.

Answer: C
Explanation:
Option C correctly creates a persistent view ('createOrReplaceView') and then grants the 'SELECT privilege to the 'PUBLIC' role. A temporary view (option B) is session-scoped and wouldn't be accessible to other users or sessions, even with a grant. Option D does not work as Global temporary views created using Snowpark API is not a supported feature..Option E does not apply the filter condition to the View.
NEW QUESTION # 162
You have written a Snowpark Python function that performs a complex calculation involving user-defined functions (UDFs). When running this function on a large dataset, you encounter a 'PicklingError: Can't pickle ': it's not the same object as main.my function'. What is the MOST likely cause of this error, and how can you resolve it?
- A. The Snowpark session is not properly initialized. Ensure that the connection parameters are correct.
- B. The UDF contains unsupported Python libraries. Ensure that all dependencies are available on the Snowflake worker nodes.
- C. The UDF is defined within a local scope or closure, and Snowpark cannot serialize it. Move the UDF definition to the global scope or use 'cloudpickle' explicitly.
- D. The dataset is too large to be processed in memory. Use 'df.cache()' to persist the intermediate results to disk.
- E. The UDF's return type is not correctly specified. Use 'udf(func, to explicitly define the return type.
Answer: C
Explanation:
Pickling errors in Snowpark often arise when UDFs are defined within local scopes because the serialization process needs to transmit the function to the Snowflake worker nodes. Moving the UDF to the global scope or using 'cloudpickle' allows the function to be correctly serialized. Option B addresses memory issues, C handles dependency problems, D addresses connection issues, and E addresses return type issues, but these are not the MOST likely cause of a PicklingError related to function scope.
NEW QUESTION # 163
You have a Snowpark DataFrame named 'sales df that contains daily sales data'. You need to calculate the weekly sales for each product and store the results in a new DataFrame. The calculation of weekly sales involves a window function that is computationally expensive. To optimize performance, you decide to cache the DataFrame after applying the window function. However, after implementing the caching, you notice that the performance is not improved as expected. What could be the reason for this and how can you fix it?
- A. The window function is not cacheable. Window functions cannot be cached using 'cache_result()'.
- B. The DataFrame is being evicted from the cache due to memory pressure. Increase the warehouse size or reduce the data being processed.
- C. Snowflake automatically optimizes window function calculations, rendering explicit caching unnecessary.
- D. The call is placed before the window function. Move the call after applying the window function.
- E. The DataFrame is too small. Caching only benefits large DataFrames.
Answer: B,D
Explanation:
The most likely reasons for the lack of performance improvement are that the DataFrame might be getting evicted from the cache due to memory constraints, rendering the caching ineffective or the cache operation placed before window operation rendering caching operation performed on raw data frame and cache operation is not useful. Increasing the warehouse size or reducing the amount of data can alleviate memory pressure. Caching before the window function would mean the expensive calculation is still being performed multiple times. Window functions can be cached after they have been executed. Snowflake does optimize queries, but explicit caching can still provide significant benefits in certain scenarios.
NEW QUESTION # 164
......
Verified SPS-C01 dumps Q&As - Pass Guarantee Exam Dumps Test Engine: https://www.prepawaypdf.com/Snowflake/SPS-C01-practice-exam-dumps.html
Verified SPS-C01 dumps and 374 unique questions: https://drive.google.com/open?id=1D3Qp9rD0YGXsBMWlgR1PSwgcsr6eoWka