

2024 Valid Databricks-Machine-Learning-Professional Real Exam Questions, practice ML Data Scientist
Latest Success Metrics For Actual Databricks-Machine-Learning-Professional Exam (Updated 62 Questions)
NEW QUESTION # 36
A machine learning engineer is in the process of implementing a concept drift monitoring solution. They are planning to use the following steps:
1. Deploy a model to production and compute predicted values
2. Obtain the observed (actual) label values
3. _____
4. Run a statistical test to determine if there are changes over time
Which of the following should be completed as Step #3?
- A. Retrain the model
- B. None of these should be completed as Step #3
- C. Compute the evaluation metric using the observed and predicted values
- D. Measure the latency of the prediction time
- E. Obtain the observed values (actual) feature values
Answer: B
NEW QUESTION # 37
Which of the following deployment paradigms can centrally compute predictions for a single record with exceedingly fast results?
- A. Streaming
- B. Batch
- C. None of these strategies will accomplish the task.
- D. Edge/on-device
- E. Real-time
Answer: A
NEW QUESTION # 38
A data scientist has created a Python function compute_features that returns a Spark DataFrame with the following schema: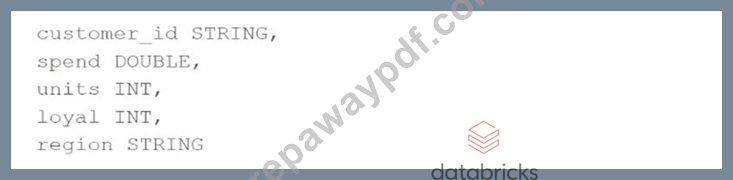
The resulting DataFrame is assigned to the features_df variable. The data scientist wants to create a Feature Store table using features_df.
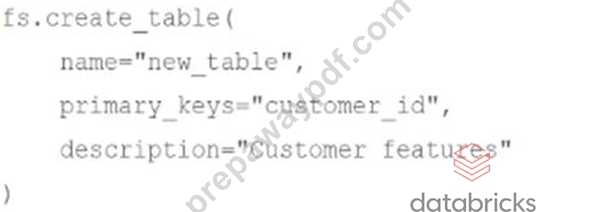
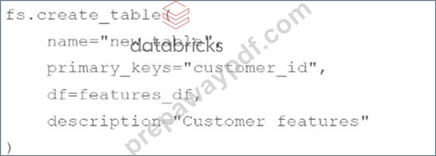
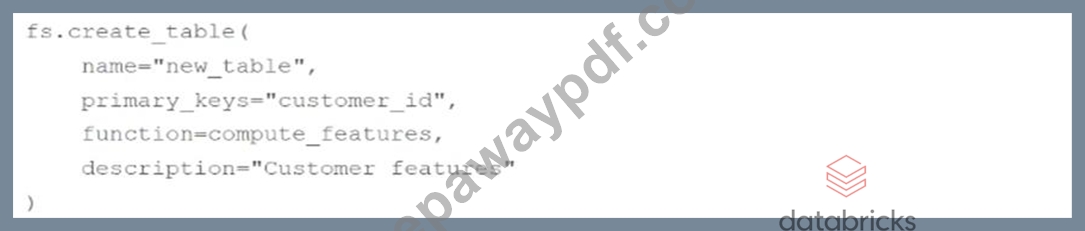
Which of the following code blocks can they use to create and populate the Feature Store table using the Feature Store Client fs?
- A.
- B. features_df.write.mode("fs").path("new_table")
- C.
- D.
- E. features_df.write.mode("feature").path("new_table")
Answer: D
NEW QUESTION # 39
A data scientist has developed a model model and computed the RMSE of the model on the test set. They have assigned this value to the variable rmse. They now want to manually store the RMSE value with the MLflow run.
They write the following incomplete code block: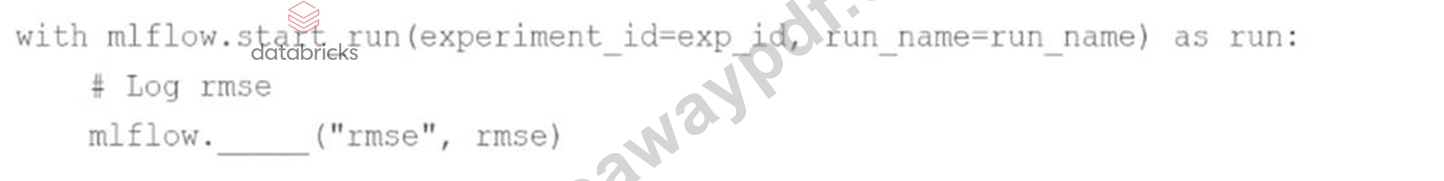
Which of the following lines of code can be used to fill in the blank so the code block can successfully complete the task?
- A. log_param
- B. log_artifact
- C. log_metric
- D. There is no way to store values like this.
- E. log_model
Answer: B
NEW QUESTION # 40
A data scientist has written a function to track the runs of their random forest model. The data scientist is changing the number of trees in the forest across each run.
Which of the following MLflow operations is designed to log single values like the number of trees in a random forest?
- A. mlflow.log_metric
- B. mlflow.log_artifact
- C. There is no way to store values like this.
- D. mlflow.log_model
- E. mlflow.log_param
Answer: A
NEW QUESTION # 41
A machine learning engineer wants to programmatically create a new Databricks Job whose schedule depends on the result of some automated tests in a machine learning pipeline.
Which of the following Databricks tools can be used to programmatically create the Job?
- A. Jobs cannot be created programmatically
- B. MLflow Client
- C. Databricks REST APIs
- D. AutoML APIs
- E. MLflow APIs
Answer: C
NEW QUESTION # 42
Which of the following MLflow Model Registry use cases requires the use of an HTTP Webhook?
- A. Starting a testing job when a new model is registered
- B. Sending an email alert when an automated testing Job fails
- C. Sending a message to a Slack channel when a model version transitions stages
- D. None of these use cases require the use of an HTTP Webhook
- E. Updating data in a source table for a Databricks SQL dashboard when a model version transitions to the Production stage
Answer: E
NEW QUESTION # 43
Which of the following machine learning model deployment paradigms is the most common for machine learning projects?
- A. None of these deployments
- B. Streaming
- C. Batch
- D. On-device
- E. Real-time
Answer: B
NEW QUESTION # 44
A machine learning engineer wants to deploy a model for real-time serving using MLflow Model Serving. For the model, the machine learning engineer currently has one model version in each of the stages in the MLflow Model Registry. The engineer wants to know which model versions can be queried once Model Serving is enabled for the model.
Which of the following lists all of the MLflow Model Registry stages whose model versions are automatically deployed with Model Serving?
- A. None. Staging. Production. Archived
- B. Staging. Production
- C. Production
- D. Staging. Production. Archived
- E. [None. Staging. Production
Answer: B
NEW QUESTION # 45
A machine learning engineer needs to deliver predictions of a machine learning model in real-time. However, the feature values needed for computing the predictions are available one week before the query time.
Which of the following is a benefit of using a batch serving deployment in this scenario rather than a real-time serving deployment where predictions are computed at query time?
- A. There is no advantage to using batch serving deployments over real-time serving deployments
- B. Computing predictions in real-time provides more up-to-date results
- C. Querying stored predictions can be faster than computing predictions in real-time
- D. Batch serving has built-in capabilities in Databricks Machine Learning
- E. Testing is not possible in real-time serving deployments
Answer: D
NEW QUESTION # 46
A machine learning engineer is converting a Hyperopt-based hyperparameter tuning process from manual MLflow logging to MLflow Autologging. They are trying to determine how to manage nested Hyperopt runs with MLflow Autologging.
Which of the following approaches will create a single parent run for the process and a child run for each unique combination of hyperparameter values when using Hyperopt and MLflow Autologging?
- A. MLflow Autoloqqinq will automatically accomplish this task with Hyperopt
- B. Ensuring that a built-in model flavor is used for the model logging
- C. Starting a manual child run within the objective function
- D. There is no way to accomplish nested runs with MLflow Autoloqqinq and Hyperopt
- E. Startinq a manual parent run before calling fmin
Answer: E
NEW QUESTION # 47
After a data scientist noticed that a column was missing from a production feature set stored as a Delta table, the machine learning engineering team has been tasked with determining when the column was dropped from the feature set.
Which of the following SQL commands can be used to accomplish this task?
- A. DESCRIBE
- B. DESCRIBE HISTORY
- C. TIMESTAMP
- D. HISTORY
- E. VERSION
Answer: B
NEW QUESTION # 48
Which of the following statements describes streaming with Spark as a model deployment strategy?
- A. The inference of all types of records in real-time
- B. The inference of batch processed records as soon as a trigger is hit
- C. The inference of incrementally processed records as soon as trigger is hit
- D. The inference of batch processed records as soon as a Spark job is run
- E. The inference of incrementally processed records as soon as a Spark job is run
Answer: E
NEW QUESTION # 49
A machine learning engineer is using the following code block as part of a batch deployment pipeline: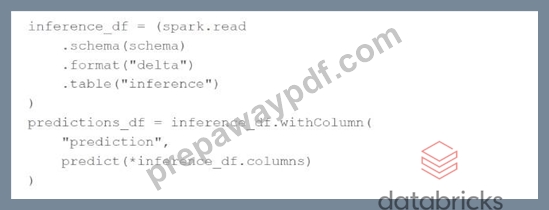
Which of the following changes needs to be made so this code block will work when the inference table is a stream source?
- A. Replace predict with a stream-friendly prediction function
- B. Replace schema(schema) with option("maxFilesPerTriqqer", 1}
- C. Replace "inference" with the path to the location of the Delta table
- D. Replace spark.read with spark.readStream
- E. Replace formatfdelta") with format("stream")
Answer: B
NEW QUESTION # 50
Which of the following is a simple statistic to monitor for categorical feature drift?
- A. None of these
- B. Percentage of missing values
- C. Mode, number of unique values, and percentage of missing values
- D. Number of unique values
- E. Mode
Answer: C
NEW QUESTION # 51
Which of the following is a benefit of logging a model signature with an MLflow model?
- A. The schema of input data will be converted to match the signature
- B. The model will be secured by the user that developed it
- C. The model will have a unique identifier in the MLflow experiment
- D. The model can be deployed using real-time serving tools
- E. The schema of input data can be validated when serving models
Answer: A
NEW QUESTION # 52
Which of the following describes the concept of MLflow Model flavors?
- A. A convention that deployment tools can use to wrap preprocessing logic into a Model
- B. A convention that MLflow Model Registry can use to version models
- C. A convention that MLflow Model Registry can use to organize its Models by project
- D. A convention that deployment tools can use to understand the model
- E. A convention that MLflow Experiments can use to organize their Runs by project
Answer: E
NEW QUESTION # 53
A data scientist has developed a scikit-learn random forest model model, but they have not yet logged model with MLflow. They want to obtain the input schema and the output schema of the model so they can document what type of data is expected as input.
Which of the following MLflow operations can be used to perform this task?
- A. mlflow.models.Model.get_input_schema
- B. mlflow.models.schema.infer_schema
- C. mlflow.models.Model.signature
- D. There is no way to obtain the input schema and the output schema of an unlogged model.
- E. mlflow.models.signature.infer_signature
Answer: B
NEW QUESTION # 54
A data scientist has computed updated feature values for all primary key values stored in the Feature Store table features. In addition, feature values for some new primary key values have also been computed. The updated feature values are stored in the DataFrame features_df. They want to replace all data in features with the newly computed data.
Which of the following code blocks can they use to perform this task using the Feature Store Client fs?
- A.
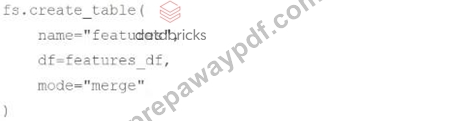
- B.
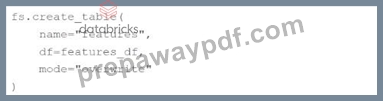
- C.
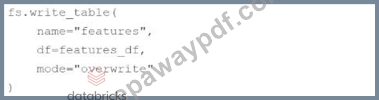
- D.
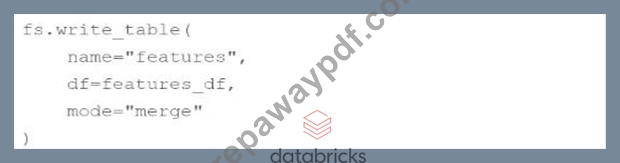
- E.
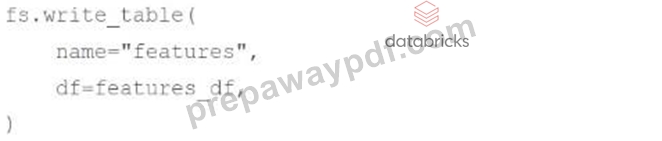
Answer: A
NEW QUESTION # 55
A data scientist is utilizing MLflow to track their machine learning experiments. After completing a series of runs for the experiment with experiment ID exp_id, the data scientist wants to programmatically work with the experiment run data in a Spark DataFrame. They have an active MLflow Client client and an active Spark session spark.
Which of the following lines of code can be used to obtain run-level results for exp_id in a Spark DataFrame?
- A. spark.read.format("delta").load(exp_id)
- B. client.list_run_infos(exp_id)
- C. spark.read.format("mlflow-experiment").load(exp_id)
- D. mlflow.search_runs(exp_id)
- E. There is no way to programmatically return row-level results from an MLflow Experiment.
Answer: A
NEW QUESTION # 56
A machine learning engineering manager has asked all of the engineers on their team to add text descriptions to each of the model projects in the MLflow Model Registry. They are starting with the model project "model" and they'd like to add the text in the model_description variable.
The team is using the following line of code: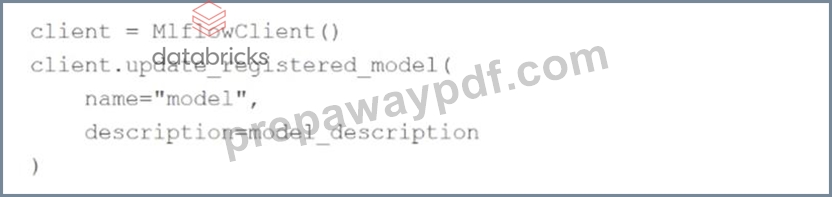
Which of the following changes does the team need to make to the above code block to accomplish the task?
- A. Replace client.update_registered_model with mlflow
- B. There no changes necessary
- C. Replace update_registered_model with update_model_version
- D. Add a Python model as an argument to update_registered_model
- E. Replace description with artifact
Answer: B
NEW QUESTION # 57
Which of the following is a probable response to identifying drift in a machine learning application?
- A. Sunsetting the machine learning application
- B. Retraining and deploying a model on more recent data
- C. Rebuilding the machine learning application with a new label variable
- D. All of these responses
- E. None of these responses
Answer: E
NEW QUESTION # 58
Which of the following MLflow operations can be used to automatically calculate and log a Shapley feature importance plot?
- A. mlflow.shap
- B. mlflow.shap.log_explanation
- C. None of these operations can accomplish the task.
- D. mlflow.log_figure
- E. client.log_artifact
Answer: A
NEW QUESTION # 59
Which of the following lists all of the model stages are available in the MLflow Model Registry?
- A. None. Staging. Production
- B. None. Staging. Production. Archived
- C. Development. Staging. Production. Archived
- D. Development. Staging. Production
- E. Staging. Production. Archived
Answer: D
NEW QUESTION # 60
......
Genuine Databricks-Machine-Learning-Professional Exam Dumps Free Demo Valid QA's: https://www.prepawaypdf.com/Databricks/Databricks-Machine-Learning-Professional-practice-exam-dumps.html
Printable & Easy to Use ML Data Scientist Databricks-Machine-Learning-Professional Dumps 100% Same Q&A In Your Real Exam: https://drive.google.com/open?id=1pkyY3fOejrbuoRDv4cnohQH8jRFlknXK